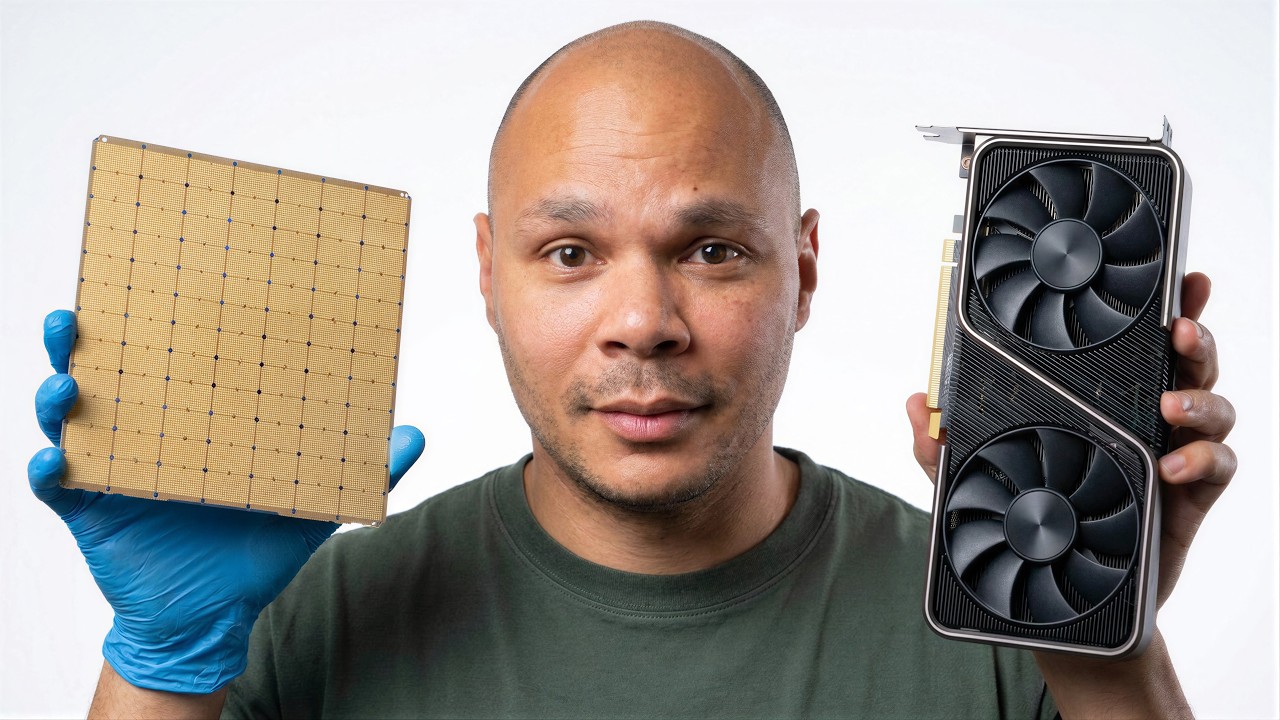
Pourquoi Nvidia a peur de ces nouvelles puces AI
Why Nvidia is afraid of these new AI chips
Title history
- Pourquoi Nvidia a peur de ces nouvelles puces AI — observed on 20261031-2318 UTC (YouTube)
Keywords
Summary
167 words
Critical Evaluation
Value of the Information & Strength of the Argument
The video provides valuable information by explaining complex hardware concepts in an accessible manner, using concrete examples and comparisons. The argumentation is structured logically, starting from the performance problem, identifying the memory bandwidth bottleneck, and then presenting various architectures that attempt to solve it. Each approach is explained with its advantages and drawbacks. However, some claims are presented without empirical evidence, such as specific token-per-second numbers, which may vary in different contexts. The reasoning is persuasive but not rigorously backed by data or citations.
Scientific Rigor, Source Quality, Title Accuracy
The video lacks explicit scientific sources; it presents information based on general knowledge and industry reports. While the technical descriptions are accurate in their main points, the absence of citations makes it difficult to verify specific figures. The title accurately reflects the content, as the video focuses on emerging AI chips that pose a threat to Nvidia’s market dominance. The content does not mislead the viewer about its scope.
168 words
Title / Content Match
The title accurately reflects the content: the video focuses on new AI chips challenging Nvidia's dominance, explaining their architectures and performance advantages.
Quality & Reliability
6/10
The video provides a clear technical overview of AI accelerator architectures, but relies on approximate figures and lacks explicit citations. The reasoning is coherent and aligns with known developments, but the absence of sources limits its reliability.
Key Moments
Markers derived by PSI from the transcript: the creator did not define chapters.
- Initial comparison of inference speed between a custom chip and ChatGPT.
- Explanation of GPUs and TPUs, including systolic arrays.
- Introduction of prefill and decode phases, and the KV cache issue.
- Groq's solution using multiple chips with large SRAM.
- Cerebras' wafer-scale chip approach.
- Talas (AMD) chip with model weights embedded.
- OpenAI's custom chip with HBM4 memory.
- Conclusion on Nvidia's advantages in flexibility and resale value.
Contribution & Novelties
The video offers a synthetic comparison of several emerging AI chip architectures (TPU, Groq, Cerebras, Talas, and OpenAI’s) focusing on how they address memory bandwidth limitations during inference. It highlights the trade-off between specialization and flexibility, concluding that Nvidia’s GPUs remain the most versatile option. The novel aspect is the clear presentation of the memory bottleneck and how different designs attempt to circumvent it.
Pour aller plus loin :
- Tensor Processing Unit — Provides background on Google’s TPU architecture.
- Groq — Details on Groq’s tensor streaming processor.
- Cerebras — Explains wafer-scale engine technology.
- Systolic array — The mathematical concept behind many AI accelerators.
103 words
Radar Profile
The technical depth (8) outshines the other scores, while information quantity (7) and reliability (6) are moderate. This suggests a highly informative but not fully substantiated video, ideal for understanding concepts but not for reference-quality facts.