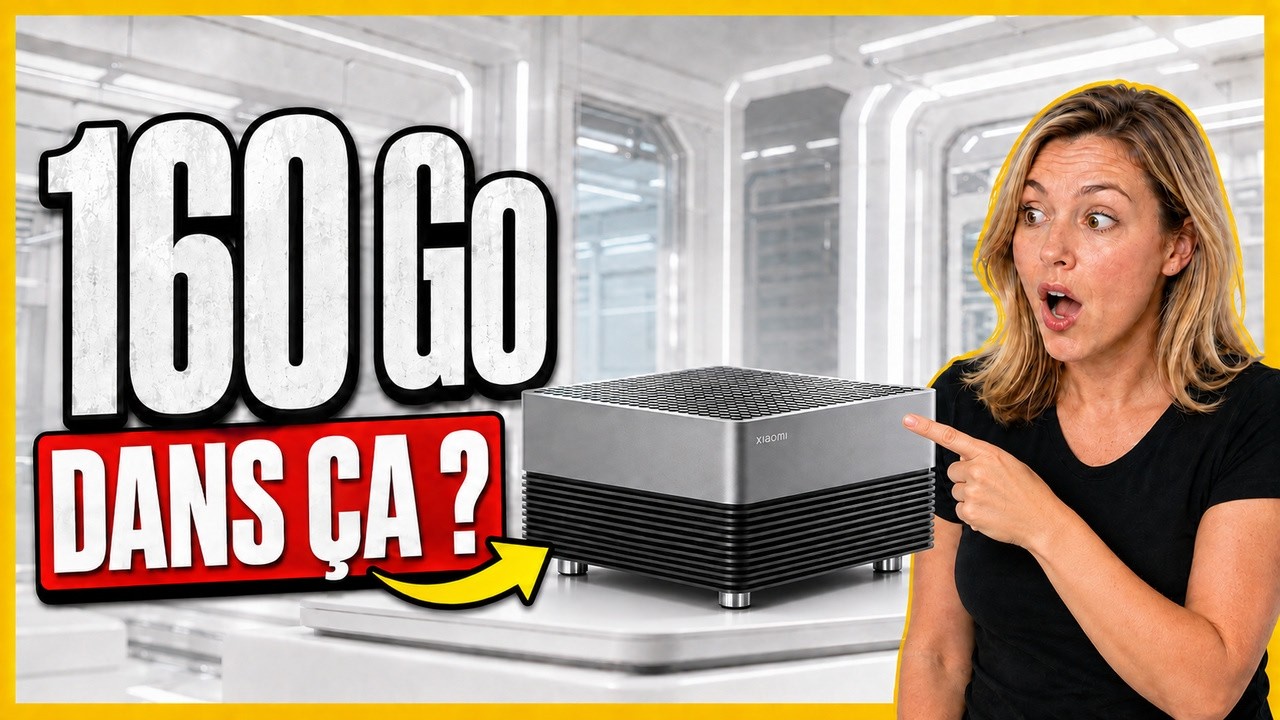
NVIDIA a PEUR: le Xiaomi AI Cube est une DINGUERIE pour l'IA locale (1,22 To/s, 160Go, 3 CPU)
NVIDIA is AFRAID: the Xiaomi AI Cube is INSANE for local AI (1.22 TB/s, 160GB, 3 CPUs)
Title history
- NVIDIA a PEUR: le Xiaomi AI Cube est une DINGUERIE pour l'IA locale (1,22 To/s, 160Go, 3 CPU) — observed on 20261101-0044 UTC (YouTube)
Keywords
Summary
184 words
Critical Evaluation
Value of the Information & Strength of the Argument
The video provides substantial technical detail about the Xiaomi AI Cube, successfully conveying the novelty of its 3D stacked architecture and the significance of achieving 1.2 TB/s bandwidth in a relatively compact 150W envelope. The creator explains the bottleneck of memory bandwidth in local AI inference and connects technical design choices to performance outcomes, strengthening the argument. Comparisons with Western platforms (AMD, Nvidia, Apple) are illustrative, though some figures are approximate and lack direct citation. The argumentation is enthusiastic but grounded in rational analysis of architectural differences, particularly the re-use of automotive processors and the potential implications for AI sovereignty. The video does not critically evaluate potential limitations or verify the claimed specifications.
Scientific Rigor, Source Quality, Title Accuracy
The video is based on information from a Xiaomi conference presentation, but no official links or technical papers are cited in the description. The creator’s analysis is generally consistent, but the lack of primary sources limits verification. The title uses a provocative tone (‘NVIDIA is AFRAID’) which may overstate the competitive threat, yet the content itself stays focused on specifications and context. The technical explanations (e.g., wafer-to-wafer bonding, hybrid bonding) are accurate, but some comparative bandwidth numbers are stated with uncertainty. Overall, the scientific rigor is moderate, suitable for a product news review, but not for an authoritative technical reference.
228 words
Title / Content Match
The title accurately reflects the content's central claim that the Xiaomi AI Cube outperforms competitors in memory bandwidth and capacity for local AI.
Quality & Reliability
6/10
The video provides detailed technical specifications from a company announcement, but relies solely on manufacturer claims without independent verification. Comparative bandwidth figures are approximate and sometimes qualified with uncertainty.
Key Moments
Markers derived by PSI from the transcript: the creator did not define chapters.
- Introduction and announcement of Xiaomi AI Cube prototype, X-Ring architecture overview.
- Details of the O3 SoC: 3nm process, 10 big cores, NPU at 200 TOPS, LPDDR6 support.
- O100 AI accelerator: 3D memory stacking, 1.2 TB/s bandwidth, 28,672 face-to-face links.
- D100 automotive processor: 3nm, 20 cores, 160GB unified memory support up to 200B-param models.
- Discussion of advanced packaging: wafer-to-wafer hybrid bonding, elimination of solder balls.
- Cooling solution: aluminum chassis with 33,874 microperforations for passive heat dissipation.
- Software and demo: HyperOS, dual-model execution with dynamic switching between 3B and 120B models.
- Bandwidth and memory comparisons with AMD, Nvidia, and Mac mini; speculation on future software support.
Contribution & Novelties
The video introduces the X-Ring architecture as a distinctive approach in the local AI hardware space, highlighting the use of heterogeneous multi-chip integration and ultra-high bandwidth memory stacking. The creator effectively explains how Xiaomi’s automotive processor heritage contributes to a high-memory-capacity AI device, a novel angle in consumer AI hardware. The discussion of face-to-face bonding and microperforation cooling adds useful technical depth.
Pour aller plus loin :
- Hybrid bonding — Explains the wafer bonding dimensions critical for such high-bandwidth interconnects.
- Neural processing unit — Context for NPU capabilities and roles in edge AI.
- Unified memory — Clarifies the concept facilitating large model loading in such devices.
106 words
Radar Profile
The radar profile shows strong scores in quantity of information and technical level, moderate quality, and lower reliability due to dependence on unverified manufacturer claims. This reflects a detailed but speculative news review rather than a peer-reviewed analysis.