[ИАД, осень 2026] Вероятностные тематические модели 1
[IAD, Fall 2026] Probabilistic Topic Models 1
Keywords
Summary
174 words
Critical Evaluation
Value of the Information & Strength of the Argument
The value of the information is high for its intended audience: it provides a solid conceptual foundation and an original perspective on topic modeling, emphasizing that the optimization viewpoint offers advantages in simplicity and flexibility over pure Bayesian methods. The argumentation is persuasive; the speaker supports his claims with historical narratives (e.g., the dominance of Bayesian models and their decline) and logical reasoning, demonstrating how the optimization formulation simplifies complex probabilistic machinery. He also argues for the relevance of topic models today, linking them to modern large language models. The arguments are coherent and logically structured, building from basic definitions to more advanced interpretations, making the case for a renewed focus on topic modeling.
Scientific Rigor, Source Quality, Title Accuracy
The scientific rigor is solid: the lecture presents well-established concepts (LDA, bag-of-words, maximum likelihood) and proposes novel connections (e.g., autoencoder interpretation), but it does not cite specific papers or provide references during the talk, except for a mention of the course webpage. The quality of sources is therefore moderate; the content is based on the speaker’s expertise and known literature, but external references are not explicitly given, limiting immediate verification. The title accurately reflects the content, and there is no mismatch; the lecture indeed covers probabilistic topic models. No comments were analyzed as none were provided.
225 words
Title / Content Match
The title accurately announces a lecture on probabilistic topic models; the content directly matches the declared subject.
Quality & Reliability
7/10
Content is technically sound, mathematically rigorous, and well-structured for a graduate-level course, but lacks explicit citations to external sources within the talk.
Key Moments
Markers derived by PSI from the transcript: the creator did not define chapters.
- Introduction to the course and its objectives
- Historical overview: from pipeline NLP to Word2Vec and transformers
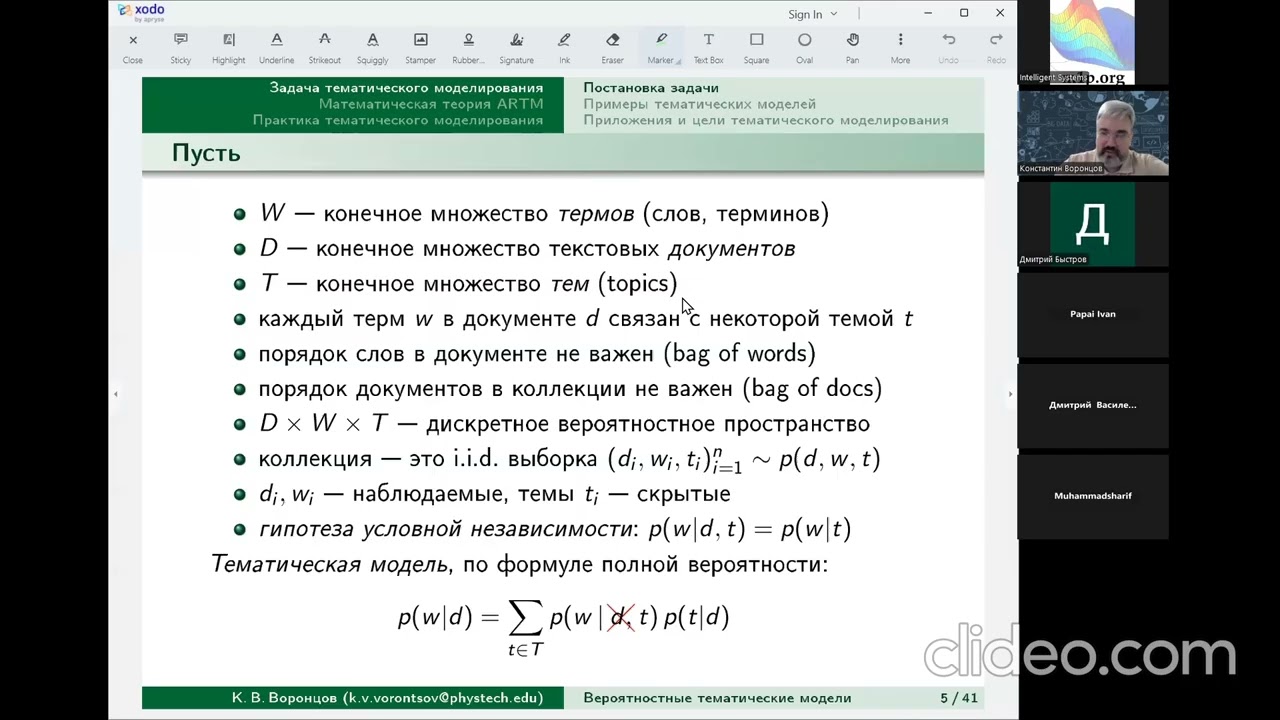
- Definition of basic sets and the bag-of-words hypothesis
- Formulation of probabilistic generative model and likelihood
- Three interpretations: soft biclustering, matrix factorization, autoencoder
- Discussion on modern directions and connection to large language models
Cited Sources
- Course page on machinelearning.ru — Mentioned as the official website for the course materials and updates
Contribution & Novelties
The lecture offers a novel pedagogical perspective by framing topic modeling as an optimization problem rather than purely Bayesian, and by highlighting the autoencoder interpretation. This reframing could inspire learners to think about topic models in a more flexible way. The speaker also teases recent research that integrates topic models with attention mechanisms, bridging classical and modern approaches.
Pour aller plus loin :
- Latent Dirichlet Allocation — Classical generative probabilistic model for topic modeling.
- Word2vec — Vector representations of words, mentioned as a milestone in text analysis.
- Transformer (machine learning model) — Architecture underlying large language models, which the speaker connects to future topic modeling.
105 words
Radar Profile
The radar profile shows a high technical level (9) and good information quantity (8), but moderate quality and reliability (7 each). This indicates the content is dense and precise but may lack external validation. The balance suggests a lecture strong in methodological depth yet with room for more explicit sourcing.