LabOS: The AI-XR Co-Scientist That Sees and Works With Humans
Keywords
Summary
164 words
Critical Evaluation
Value of the Information & Strength of the Argument
The talk’s value lies in highlighting the often-overlooked bottleneck of experimental verification in AI-driven science. The argument is well-structured: it starts with the theoretical limitations of RL in simulated environments, then presents statistical evidence of the reproducibility crisis, and proposes a concrete infrastructure—LabOS—to bridge the gap. The speaker convincingly argues that real-world interaction is necessary for true innovation, and the system’s design, integrating XR, vision models, and RL, is a plausible step forward. However, the argumentation is constrained by the informal format and time limits, leaving several technical components underexplained. The Q&A partially addresses these gaps, though the speaker admits the system is not yet generalized across all experimental types.
Scientific Rigor, Source Quality, Title Accuracy
The talk references a PNAS paper on AI exploration, a preprint on arXiv, and the Nature submission for LabOS, but no direct URLs are provided beyond the Simons Institute page. The scientific rigor is reasonable for a workshop talk: it relies on established RL concepts and recent studies, though the speaker does not detail the methodology or evaluation metrics thoroughly. The title accurately reflects the content, as it emphasizes the AI-XR co-scientist aspect. The talk page from Simons serves as a reliable source, and the context of the Trustworthy AI program adds credibility. The informal delivery and occasional off-topic discussions slightly detract from the focus, but overall the content is coherent and well-motivated.
238 words
Title / Content Match
The title accurately captures the system's purpose: an AI co-scientist that uses XR to perceive and collaborate with human experimenters.
Quality & Reliability
8/10
High credibility due to prestigious academic setting (Simons Institute, Stanford, Princeton), but the talk is informal and substitutes for the original speaker, limiting technical depth.
Key Moments
Markers derived by PSI from the transcript: the creator did not define chapters.
- Kuang Xu explains he is substituting for Mengdi Wang and gives background on the LabOS project collaboration.
- Introduction of the overarching question: how can reinforcement learning scale science, and the need for physical-world interaction.
- Description of the three loops: thinking, doing, and measuring/verification in LabOS.
- Discussion of exploration challenges in real-world science, referencing bandit problems and the difficulty of defining 'arms' in physical experiments.
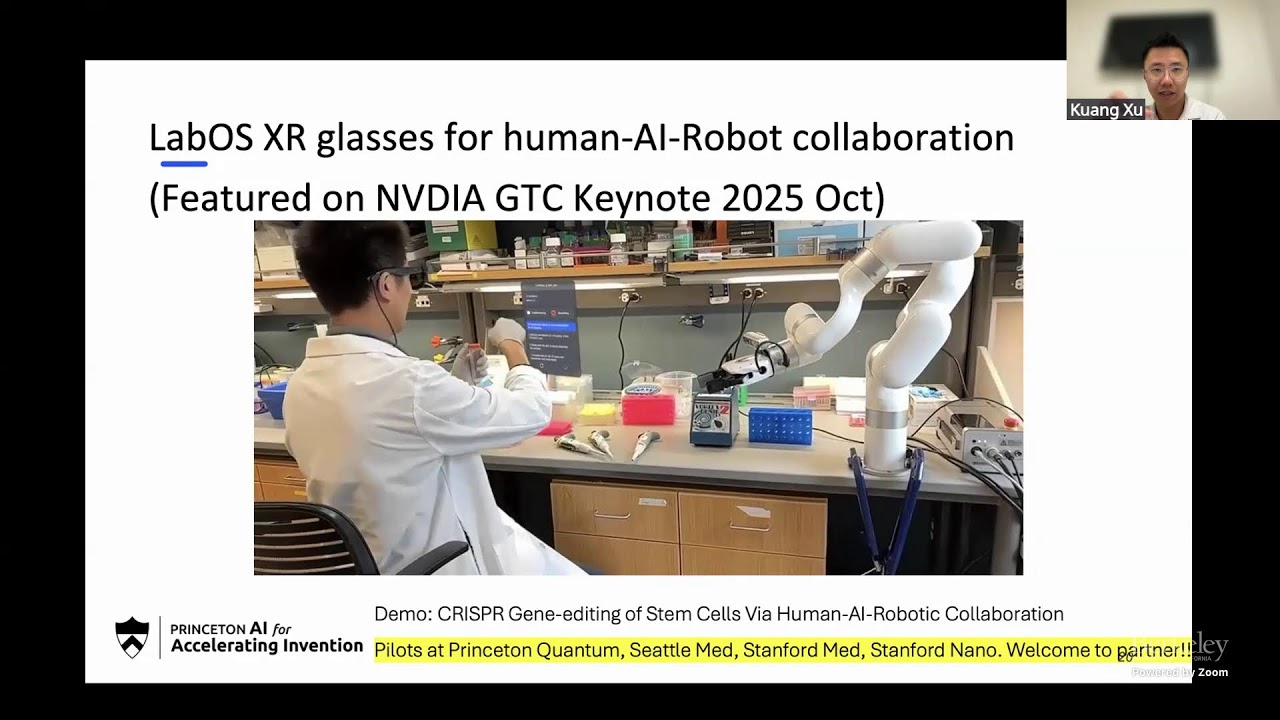
- Demo of the LabOS system: XR goggles guide a novice scientist through CRISPR gene editing, with the agentic layer providing real-time instructions and verification.
- Q&A session: clarification of the verification definition and the goal of building a general laboratory co-scientist, with ongoing work on 4D world models and trace data training.
Cited Sources
- Simons Institute Talk Page — Official page for the talk, part of the Trustworthy AI: From Hallucinations to Reliable Autonomy program.
Contribution & Novelties
The main novelty of LabOS is the integration of XR and AI to provide real-time guidance and verification in physical laboratory experiments, addressing the verification bottleneck in scientific research. The system’s 4D world model pipeline and the collection of annotated scientific traces for training specialized foundation models represent a significant step toward closing the loop between digital reasoning and physical action. The talk also underscores the importance of out-of-distribution exploration and the need to move beyond reward-seeking in static simulations.
Pour aller plus loin :
- Reinforcement learning — Core technique used for iterative improvement in LabOS, though the talk extends it to real-world feedback.
- Digital twin — The 4D world model is a form of digital twin, enabling simulation and reasoning over laboratory environments.
- Replication crisis — The statistical evidence cited in the talk aligns with the broader issue of reproducibility in science, motivating the need for automated verification.
149 words
Radar Profile
The profile shows balanced scores, with slightly lower quantitative information due to the informal talk and time constraints, but strong quality and reliability from the academic context. The technical level is moderate, reflecting a high-level overview rather than deep technical details.