CS 471/671 (How to grow language models) - #9 - Fall 2026
Keywords
Summary
170 words
Critical Evaluation
Value of the Information & Strength of the Argument
VALUE: The lecture provides a solid, practical understanding of tokenization, an often-underappreciated component of language models. Using the OpenAI tokenizer interactively gives concrete insights into real-world behavior, while the hand-coded BPE example clarifies the training mechanism in a way that abstract descriptions rarely achieve. ARGUMENTATION: The argumentation is logical and incremental: it starts by motivating subword tokenization via the drawbacks of character and word levels, then decomposes the pipeline into clearly separated stages, and finally drills down into the BPE algorithm with a traceable example. The instructor addresses student questions on implementation details, such as merging rules and space handling, reinforcing the reasoning behind design choices.
Scientific Rigor, Source Quality, Title Accuracy
SCIENTIFIC RIGOR: The content is based on established algorithms (BPE) and standard NLP practices. The instructor accurately explains trade-offs and openly discusses limitations, such as normalization costs and the arbitrary nature of token boundaries. SOURCES: The only cited external resource is the official course page, which is appropriate. The lecture relies on well-known examples (OpenAI tokenizer) and does not introduce unsupported claims. ADEQUATION TITRE: The title indicates a course on growing language models, and this session on tokenization is a fundamental part of that process; the lecture matches the expected scope, though it is a specific subtopic rather than a broad overview.
223 words
Title / Content Match
The title suggests a course on growing language models; this lecture specifically addresses tokenization, a core component of building language models, so the content aligns well with the course theme.
Quality & Reliability
9/10
University lecture by a reputable institution (JHU CLSP) covering established algorithms (BPE) with clear demonstrations and accurate technical details.
Key Moments
Markers derived by PSI from the transcript: the creator did not define chapters.
- Recap of tokenization trade-offs and introduction to subword tokenization.
- Live demo of OpenAI's tokenizer on sample text, showing token splitting and special handling of numbers and spaces.
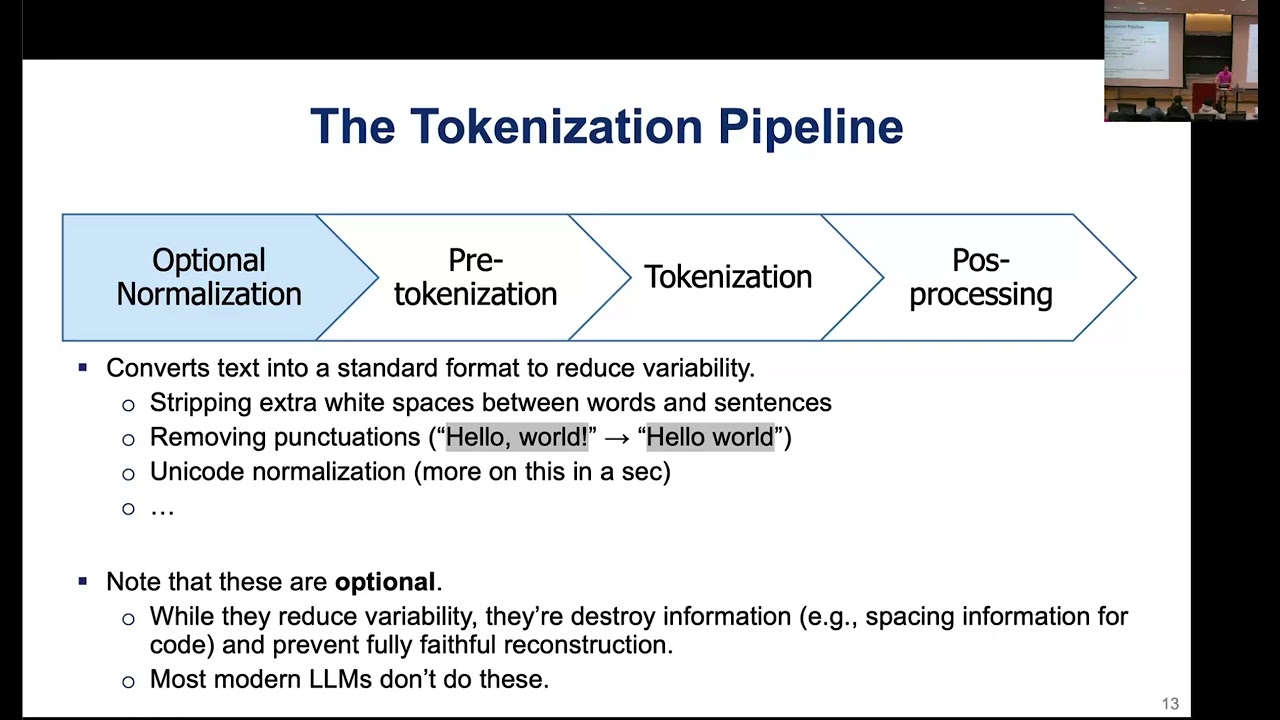
- Detailed explanation of the tokenization pipeline: normalization (NFKC), pre-tokenization into chunks, and post-processing steps.
- Step-by-step walkthrough of BPE training on a small corpus, including pair counting and merging iteration.
- Discussion of scalability, efficient data structures for pair counting, and handling of spaces in BPE; Q&A session.
Cited Sources
- CS 471/671 Fall 2026 Course Page — Official course page providing syllabus, materials, and context for the lecture series.
Contribution & Novelties
This lecture provides an accessible yet thorough introduction to tokenization and BPE, bridging theory and practice. The interactive demo with a real tokenizer and the hand-computed training example offer immediate understanding that typical textbook descriptions may lack. It emphasizes practical considerations like normalization choices and space handling, which are often glossed over.
Pour aller plus loin :
- Byte pair encoding — Foundational algorithm behind subword tokenizers; the lecture’s core topic.
- Subword tokenization — Broader context; includes BPE, WordPiece, and SentencePiece.
- Unicode normalization — Mentioned in the lecture as an optional pre-tokenization step; explains NFKC and related forms.
97 words
Radar Profile
The profile shows balanced strengths: high information quantity and quality, with strong technical depth and reliability. The lecture excels in explaining a complex algorithm clearly, making it a valuable resource for learners.